
Agentic AI / Hackathon
FairSprint AI
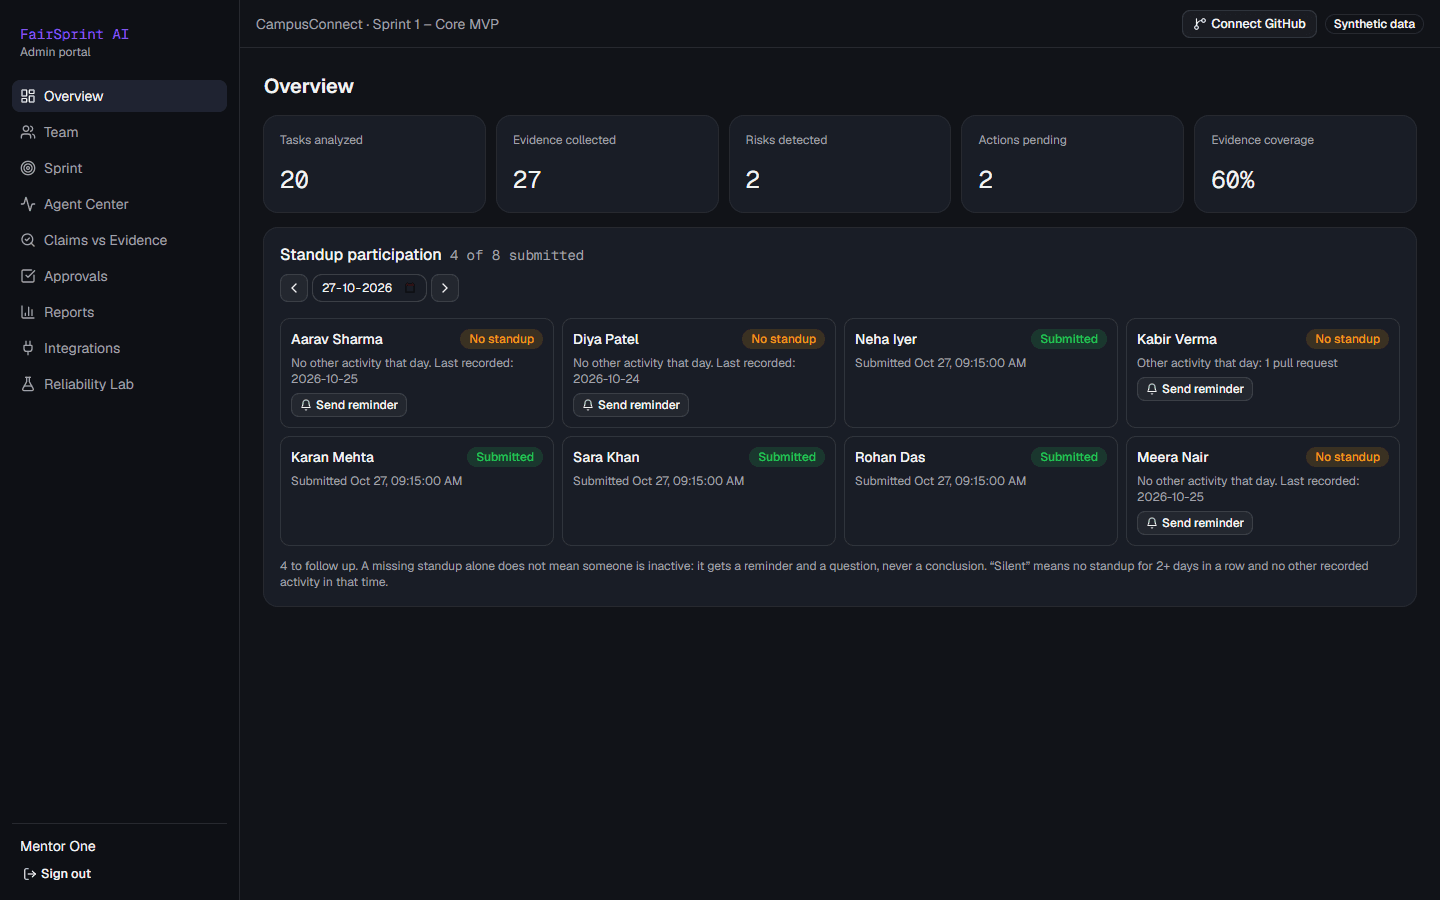
Agent that checks what team members say they did against the evidence that exists, with a mentor approving every consequential change.
[01] problem
Mentors must judge team progress they mostly cannot see, and commit counts under-count reviewers, testers, writers and designers.
[02] approach
- 01A LangGraph agent loads each member's standup claim and collects evidence from Supabase and read-only GitHub activity.
- 02Deterministic code assigns one of four verification statuses (verified, partially verified, unverified, insufficient evidence), classifies risk and proposes reassignments with capacity and dependency checks.
- 03The run pauses for mentor approval; approving a reassignment applies it once, rejecting changes nothing, and the last decision resumes the run to draft the weekly report.
[03] what's interesting
- Verification is deterministic code, not the language model, and the model's output is validated against schemas.
- A missing API response is never treated as proof of no activity, and no output is worded as a finding of misconduct.
- Gemini is the primary model with Groq as an independent fallback.
[04] stack
- Python
- FastAPI
- LangGraph
- React 19
- TypeScript
- Supabase
- Gemini
- Groq